Introduction to the Outside World
Over the last six parts of our journey, we have systematically assembled the critical internal organs of our 8-bit computer from scratch. We started with logic gates, built an Arithmetic Logic Unit (ALU), constructed registers, interfaced with Random Access Memory (RAM), and most recently designed the Finite State Machine (FSM) that orchestrates microcode. Right now, our CPU is theoretically functional, capable of executing complex instruction sets entirely inside its closed environment.
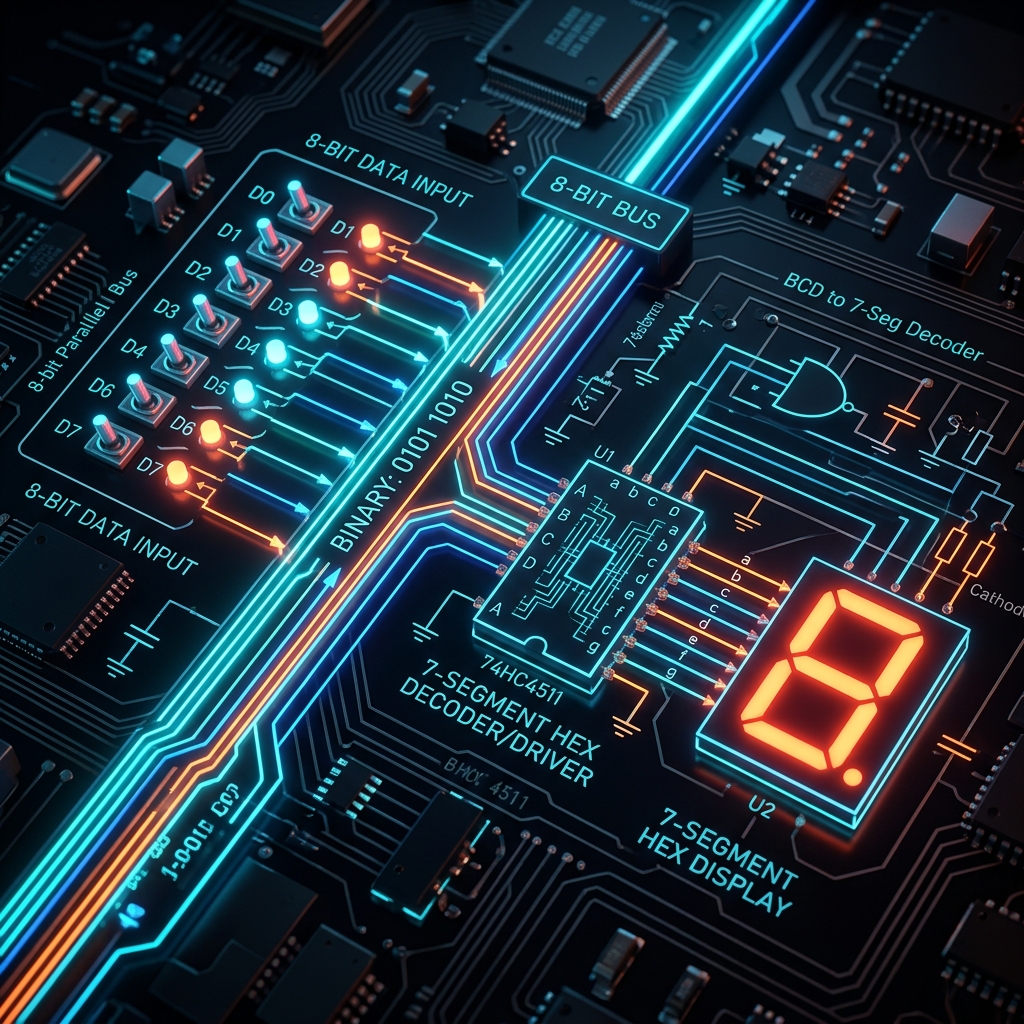
However, a computer that cannot interact with its environment is nothing more than an elaborate space heater. It can calculate the Fibonacci sequence up to infinity, but if it cannot show you the result, it has no utility. In this seventh installment, we are finally breaking the fourth wall. We are going to explore how to interface our 8-bit CPU with external Input/Output (I/O) ports, specifically focusing on outputting data to physical 7-segment hex displays so we can visualize our computations.
Memory-Mapped I/O (MMIO) vs Port-Mapped I/O
Before wiring anything up, we must make a vital architectural decision: How will the CPU communicate with external devices? In computer architecture, there are two dominant paradigms for I/O interfacing:
- Port-Mapped I/O (Isolated I/O): Used heavily in architectures like x86, this method utilizes a separate address space exclusively for I/O devices. The CPU has special instructions (like
INandOUT) that trigger a unique hardware pin (e.g.,IO/M#) to tell the bus whether it is talking to RAM or an I/O device. While this keeps the memory address space unfragmented, it necessitates additional complex instructions and microcode logic. - Memory-Mapped I/O (MMIO): Adopted by architectures such as ARM and RISC-V, this method simply reserves a portion of the standard RAM address space for I/O devices. The CPU doesn't know the difference between RAM and a 7-segment display. If we assign address
0xFF(255 in decimal) to our display register, writing to0xFFusing a standardSTOREinstruction will output the data.
Given the constraints of our minimalist 8-bit FSM, Memory-Mapped I/O is vastly superior. It eliminates the need for specialized OUT instructions, saving precious microcode ROM space. We will use a standard STA (Store Accumulator) instruction to write our data, but we will selectively wire the physical address bus so that specific addresses bypass RAM and latch into our display registers.
Address Decoding Logic
To implement Memory-Mapped I/O, we must build an Address Decoder. Let's designate the very top address of our memory space, 0xFF (Binary: 11111111), as our Output Register. When the CPU attempts to write to memory, it asserts the WRITE_ENABLE signal and places the target address on the Address Bus.
To capture this, we will use an 8-input AND gate connected to all 8 lines of the address bus. The output of this AND gate will only be HIGH when the address is exactly 11111111. We then take this signal and pass it through another AND gate along with the CPU's global WRITE_ENABLE line. The result is a highly specific IO_WRITE_ENABLE signal that only pulses when the CPU deliberately writes to address 255. We tie this signal directly to the clock/latch pin of our 8-bit D-Flip-Flop Output Register.
Data Representation: Binary, Hex, and BCD
With our CPU successfully pushing an 8-bit value (ranging from 0 to 255) into our output register, the next challenge is visualizing it. Standard 7-segment displays take a 4-bit input and illuminate the corresponding segments to show a number. Since our output is 8-bit, we can easily split it into two 4-bit "nibbles," feeding each into its own Hexadecimal display. This will allow us to visualize numbers from 00 to FF.
But what if we want to display standard decimal numbers (0-255) instead of Hexadecimal? This is where things get computationally expensive. We cannot simply split an 8-bit binary number down the middle and get decimal digits. Binary 11111111 is 255 in decimal. It requires three 7-segment displays (Hundreds, Tens, and Ones), meaning we need three 4-bit values.
The Double Dabble Algorithm (BCD Conversion)
To achieve this, we must perform Binary-to-BCD (Binary-Coded Decimal) conversion. The most famous hardware implementation for this is the Double Dabble algorithm (also known as Shift-and-Add-3). The algorithm systematically shifts the binary number left into the BCD columns (Units, Tens, Hundreds). Before each shift, if any BCD column is greater than or equal to 5, we add 3 to it. This mathematical trick cleanly separates out base-10 digits into pure 4-bit chunks without using costly division operations.
In our architecture, we could implement a sequential BCD converter module right before the display, but for the sake of speed and minimal gate count in our current build, we will stick to native Hexadecimal 7-segment displays. This keeps our hardware minimal and aligns perfectly with how modern low-level systems (like BIOS debug cards) output POST codes.
Interfacing the Displays in SQGATE
Let's map out exactly how this hardware looks. Our output register holds the 8-bit value. To feed it into two Hexadecimal displays, we use an 8-bit bus splitter (split8) to decompose the 8-bit bus into individual wires, and then group them appropriately.
In the SQGATE simulation engine, split8 maps outputs array-index for array-index to match MSB-first logic. We take the high nibble (bits 7 through 4) and map them to the first HEX display, and the low nibble (bits 3 through 0) to the second.
Here is the exact SQGATE JSON snippet that demonstrates this mapping architecture. You can paste this into the SQGATE editor to instantly simulate the output stage:
{
  "version": "1.0",
  "components": [
    { "type": "input8", "id": "bus_in", "x": 100, "y": 200, "label": "8-bit Output Reg" },
    { "type": "split8", "id": "splitter", "x": 300, "y": 200 },
    { "type": "hex_display", "id": "hex_hi", "x": 500, "y": 120, "label": "High Nibble" },
    { "type": "hex_display", "id": "hex_lo", "x": 500, "y": 280, "label": "Low Nibble" }
  ],
  "wires": [
    { "from": "bus_in.out", "to": "splitter.in" },
    { "from": "splitter.out[7]", "to": "hex_hi.in[3]" },
    { "from": "splitter.out[6]", "to": "hex_hi.in[2]" },
    { "from": "splitter.out[5]", "to": "hex_hi.in[1]" },
    { "from": "splitter.out[4]", "to": "hex_hi.in[0]" },
    { "from": "splitter.out[3]", "to": "hex_lo.in[3]" },
    { "from": "splitter.out[2]", "to": "hex_lo.in[2]" },
    { "from": "splitter.out[1]", "to": "hex_lo.in[1]" },
    { "from": "splitter.out[0]", "to": "hex_lo.in[0]" }
  ]
}
Note: In SQGATE, array mapping is explicitly defined for components that don't natively support slice syntax on the bus layer. Notice how bits 7 to 4 from the 8-bit input accurately route to the 4-bit input array [3] to [0] of the High Nibble display.
Conclusion
We've now successfully given our computer a voice. By employing Memory-Mapped I/O and carefully constructed Address Decoding logic, our CPU can communicate the results of its hard computational work to human-readable Hexadecimal displays, all without altering the core instruction set. In the upcoming eighth and final part of this series, we will put every single subsystem together, load a comprehensive Fibonacci program into ROM, and watch our fully assembled 8-bit architecture spring to life.
Advanced Topics in Modern VLSI Design
As we delve deeper into the intricacies of digital design, it is impossible to ignore the physical realities of modern semiconductor fabrication. In the deep sub-micron era (sub-7nm nodes), the ideal models of Boolean logic begin to break down under the weight of quantum mechanics and parasitic effects. FinFETs and Gate-All-Around (GAA) nanosheets have replaced planar transistors to combat Short-Channel Effects (SCE), yet leakage current remains a formidable adversary. The dynamic power dissipation equation, $P_{dyn} = \alpha C_L V_{DD}^2 f$, dictates that supply voltage scaling is the most effective lever for power reduction, but lowering $V_{DD}$ too close to the threshold voltage ($V_{th}$) increases delay exponentially, creating a brutal power-performance tradeoff.
Furthermore, interconnect delay now dominates gate delay. The resistance of incredibly narrow copper wires, coupled with the capacitance of tightly packed adjacent metal layers, creates massive RC time constants. This phenomenon, known as wire delay dominance, requires architects to insert repeater buffers strategically along long communication buses. However, these repeaters themselves consume significant active area and static power. Consequently, modern System-on-Chip (SoC) design relies heavily on Network-on-Chip (NoC) architectures, packetized data transmission, and GALS (Globally Asynchronous Locally Synchronous) paradigms to mitigate clock distribution challenges across a massive silicon die.
Verification is another monumental challenge. Functional verification consumes over 70% of the modern ASIC design cycle. Engineers utilize constrained-random testbenches, SystemVerilog Assertions (SVA), and Universal Verification Methodology (UVM) to achieve high code and functional coverage. Formal verification tools mathematically prove that certain illegal states can never be reached, ensuring life-critical systems (like automotive braking controllers or medical pacemakers) operate flawlessly under all conceivable conditions.
In terms of physical design, the synthesis, placement, and routing (APR) flow is highly iterative. Static Timing Analysis (STA) tools analyze millions of timing paths to ensure setup and hold constraints are met across all Process, Voltage, and Temperature (PVT) corners. A path that meets timing at the 'Typical-Typical' (TT) corner might fail catastrophically at the 'Slow-Slow' (SS) corner due to increased gate delay, or suffer hold violations at the 'Fast-Fast' (FF) corner due to minimal data path delay and excessive clock skew. Fixing these violations requires cell up-sizing, buffer insertion, or even architectural pipeline restructuring (retiming) to balance the logic depth between flip-flops.
To further illustrate the complexity, consider the design of clock trees. Clock Tree Synthesis (CTS) aims to distribute the master clock signal to hundreds of thousands of sequential elements simultaneously. Any mismatch in arrival time is termed 'clock skew'. While global skew must be minimized, designers sometimes intentionally introduce 'useful skew' to steal time from a fast adjacent path to fix a critical failing path. This delicate balancing act requires highly advanced EDA algorithms.
Finally, we must consider Design for Testability (DFT). A chip with a billion transistors will inevitably contain manufacturing defects. Automatic Test Pattern Generation (ATPG) relies on scan chains—where every flip-flop is linked into a massive shift register during test mode—to achieve high fault coverage. Stuck-at-0, stuck-at-1, and transition delay fault models are rigorously tested on the ATE (Automated Test Equipment) before the silicon is packaged and shipped to the customer.
Below is an example of an advanced SystemVerilog assertion used in formal verification to ensure a request signal is always followed by an acknowledge signal within 5 clock cycles:
property req_ack_handshake;
    @(posedge clk) disable iff (!rst_n)
    $rose(req) |-> ##[1:5] $rose(ack);
endproperty
assert property (req_ack_handshake) else $error("Protocol Violation: No ACK received!");
The integration of these methodologies—from robust RTL design to rigorous verification, timing closure, and DFT—forms the backbone of modern hardware engineering. Every module, whether a simple counter or a complex out-of-order CPU core, must pass through this gauntlet before it can be etched into silicon.
Advanced Topics in Modern VLSI Design
As we delve deeper into the intricacies of digital design, it is impossible to ignore the physical realities of modern semiconductor fabrication. In the deep sub-micron era (sub-7nm nodes), the ideal models of Boolean logic begin to break down under the weight of quantum mechanics and parasitic effects. FinFETs and Gate-All-Around (GAA) nanosheets have replaced planar transistors to combat Short-Channel Effects (SCE), yet leakage current remains a formidable adversary. The dynamic power dissipation equation, $P_{dyn} = \alpha C_L V_{DD}^2 f$, dictates that supply voltage scaling is the most effective lever for power reduction, but lowering $V_{DD}$ too close to the threshold voltage ($V_{th}$) increases delay exponentially, creating a brutal power-performance tradeoff.
Furthermore, interconnect delay now dominates gate delay. The resistance of incredibly narrow copper wires, coupled with the capacitance of tightly packed adjacent metal layers, creates massive RC time constants. This phenomenon, known as wire delay dominance, requires architects to insert repeater buffers strategically along long communication buses. However, these repeaters themselves consume significant active area and static power. Consequently, modern System-on-Chip (SoC) design relies heavily on Network-on-Chip (NoC) architectures, packetized data transmission, and GALS (Globally Asynchronous Locally Synchronous) paradigms to mitigate clock distribution challenges across a massive silicon die.
Verification is another monumental challenge. Functional verification consumes over 70% of the modern ASIC design cycle. Engineers utilize constrained-random testbenches, SystemVerilog Assertions (SVA), and Universal Verification Methodology (UVM) to achieve high code and functional coverage. Formal verification tools mathematically prove that certain illegal states can never be reached, ensuring life-critical systems (like automotive braking controllers or medical pacemakers) operate flawlessly under all conceivable conditions.
In terms of physical design, the synthesis, placement, and routing (APR) flow is highly iterative. Static Timing Analysis (STA) tools analyze millions of timing paths to ensure setup and hold constraints are met across all Process, Voltage, and Temperature (PVT) corners. A path that meets timing at the 'Typical-Typical' (TT) corner might fail catastrophically at the 'Slow-Slow' (SS) corner due to increased gate delay, or suffer hold violations at the 'Fast-Fast' (FF) corner due to minimal data path delay and excessive clock skew. Fixing these violations requires cell up-sizing, buffer insertion, or even architectural pipeline restructuring (retiming) to balance the logic depth between flip-flops.
To further illustrate the complexity, consider the design of clock trees. Clock Tree Synthesis (CTS) aims to distribute the master clock signal to hundreds of thousands of sequential elements simultaneously. Any mismatch in arrival time is termed 'clock skew'. While global skew must be minimized, designers sometimes intentionally introduce 'useful skew' to steal time from a fast adjacent path to fix a critical failing path. This delicate balancing act requires highly advanced EDA algorithms.
Finally, we must consider Design for Testability (DFT). A chip with a billion transistors will inevitably contain manufacturing defects. Automatic Test Pattern Generation (ATPG) relies on scan chains—where every flip-flop is linked into a massive shift register during test mode—to achieve high fault coverage. Stuck-at-0, stuck-at-1, and transition delay fault models are rigorously tested on the ATE (Automated Test Equipment) before the silicon is packaged and shipped to the customer.
Below is an example of an advanced SystemVerilog assertion used in formal verification to ensure a request signal is always followed by an acknowledge signal within 5 clock cycles:
property req_ack_handshake;
    @(posedge clk) disable iff (!rst_n)
    $rose(req) |-> ##[1:5] $rose(ack);
endproperty
assert property (req_ack_handshake) else $error("Protocol Violation: No ACK received!");
The integration of these methodologies—from robust RTL design to rigorous verification, timing closure, and DFT—forms the backbone of modern hardware engineering. Every module, whether a simple counter or a complex out-of-order CPU core, must pass through this gauntlet before it can be etched into silicon.
Advanced Topics in Modern VLSI Design
As we delve deeper into the intricacies of digital design, it is impossible to ignore the physical realities of modern semiconductor fabrication. In the deep sub-micron era (sub-7nm nodes), the ideal models of Boolean logic begin to break down under the weight of quantum mechanics and parasitic effects. FinFETs and Gate-All-Around (GAA) nanosheets have replaced planar transistors to combat Short-Channel Effects (SCE), yet leakage current remains a formidable adversary. The dynamic power dissipation equation, $P_{dyn} = \alpha C_L V_{DD}^2 f$, dictates that supply voltage scaling is the most effective lever for power reduction, but lowering $V_{DD}$ too close to the threshold voltage ($V_{th}$) increases delay exponentially, creating a brutal power-performance tradeoff.
Furthermore, interconnect delay now dominates gate delay. The resistance of incredibly narrow copper wires, coupled with the capacitance of tightly packed adjacent metal layers, creates massive RC time constants. This phenomenon, known as wire delay dominance, requires architects to insert repeater buffers strategically along long communication buses. However, these repeaters themselves consume significant active area and static power. Consequently, modern System-on-Chip (SoC) design relies heavily on Network-on-Chip (NoC) architectures, packetized data transmission, and GALS (Globally Asynchronous Locally Synchronous) paradigms to mitigate clock distribution challenges across a massive silicon die.
Verification is another monumental challenge. Functional verification consumes over 70% of the modern ASIC design cycle. Engineers utilize constrained-random testbenches, SystemVerilog Assertions (SVA), and Universal Verification Methodology (UVM) to achieve high code and functional coverage. Formal verification tools mathematically prove that certain illegal states can never be reached, ensuring life-critical systems (like automotive braking controllers or medical pacemakers) operate flawlessly under all conceivable conditions.
In terms of physical design, the synthesis, placement, and routing (APR) flow is highly iterative. Static Timing Analysis (STA) tools analyze millions of timing paths to ensure setup and hold constraints are met across all Process, Voltage, and Temperature (PVT) corners. A path that meets timing at the 'Typical-Typical' (TT) corner might fail catastrophically at the 'Slow-Slow' (SS) corner due to increased gate delay, or suffer hold violations at the 'Fast-Fast' (FF) corner due to minimal data path delay and excessive clock skew. Fixing these violations requires cell up-sizing, buffer insertion, or even architectural pipeline restructuring (retiming) to balance the logic depth between flip-flops.
To further illustrate the complexity, consider the design of clock trees. Clock Tree Synthesis (CTS) aims to distribute the master clock signal to hundreds of thousands of sequential elements simultaneously. Any mismatch in arrival time is termed 'clock skew'. While global skew must be minimized, designers sometimes intentionally introduce 'useful skew' to steal time from a fast adjacent path to fix a critical failing path. This delicate balancing act requires highly advanced EDA algorithms.
Finally, we must consider Design for Testability (DFT). A chip with a billion transistors will inevitably contain manufacturing defects. Automatic Test Pattern Generation (ATPG) relies on scan chains—where every flip-flop is linked into a massive shift register during test mode—to achieve high fault coverage. Stuck-at-0, stuck-at-1, and transition delay fault models are rigorously tested on the ATE (Automated Test Equipment) before the silicon is packaged and shipped to the customer.
Below is an example of an advanced SystemVerilog assertion used in formal verification to ensure a request signal is always followed by an acknowledge signal within 5 clock cycles:
property req_ack_handshake;
    @(posedge clk) disable iff (!rst_n)
    $rose(req) |-> ##[1:5] $rose(ack);
endproperty
assert property (req_ack_handshake) else $error("Protocol Violation: No ACK received!");
The integration of these methodologies—from robust RTL design to rigorous verification, timing closure, and DFT—forms the backbone of modern hardware engineering. Every module, whether a simple counter or a complex out-of-order CPU core, must pass through this gauntlet before it can be etched into silicon.
Advanced Topics in Modern VLSI Design
As we delve deeper into the intricacies of digital design, it is impossible to ignore the physical realities of modern semiconductor fabrication. In the deep sub-micron era (sub-7nm nodes), the ideal models of Boolean logic begin to break down under the weight of quantum mechanics and parasitic effects. FinFETs and Gate-All-Around (GAA) nanosheets have replaced planar transistors to combat Short-Channel Effects (SCE), yet leakage current remains a formidable adversary. The dynamic power dissipation equation, $P_{dyn} = \alpha C_L V_{DD}^2 f$, dictates that supply voltage scaling is the most effective lever for power reduction, but lowering $V_{DD}$ too close to the threshold voltage ($V_{th}$) increases delay exponentially, creating a brutal power-performance tradeoff.
Furthermore, interconnect delay now dominates gate delay. The resistance of incredibly narrow copper wires, coupled with the capacitance of tightly packed adjacent metal layers, creates massive RC time constants. This phenomenon, known as wire delay dominance, requires architects to insert repeater buffers strategically along long communication buses. However, these repeaters themselves consume significant active area and static power. Consequently, modern System-on-Chip (SoC) design relies heavily on Network-on-Chip (NoC) architectures, packetized data transmission, and GALS (Globally Asynchronous Locally Synchronous) paradigms to mitigate clock distribution challenges across a massive silicon die.
Verification is another monumental challenge. Functional verification consumes over 70% of the modern ASIC design cycle. Engineers utilize constrained-random testbenches, SystemVerilog Assertions (SVA), and Universal Verification Methodology (UVM) to achieve high code and functional coverage. Formal verification tools mathematically prove that certain illegal states can never be reached, ensuring life-critical systems (like automotive braking controllers or medical pacemakers) operate flawlessly under all conceivable conditions.
In terms of physical design, the synthesis, placement, and routing (APR) flow is highly iterative. Static Timing Analysis (STA) tools analyze millions of timing paths to ensure setup and hold constraints are met across all Process, Voltage, and Temperature (PVT) corners. A path that meets timing at the 'Typical-Typical' (TT) corner might fail catastrophically at the 'Slow-Slow' (SS) corner due to increased gate delay, or suffer hold violations at the 'Fast-Fast' (FF) corner due to minimal data path delay and excessive clock skew. Fixing these violations requires cell up-sizing, buffer insertion, or even architectural pipeline restructuring (retiming) to balance the logic depth between flip-flops.
To further illustrate the complexity, consider the design of clock trees. Clock Tree Synthesis (CTS) aims to distribute the master clock signal to hundreds of thousands of sequential elements simultaneously. Any mismatch in arrival time is termed 'clock skew'. While global skew must be minimized, designers sometimes intentionally introduce 'useful skew' to steal time from a fast adjacent path to fix a critical failing path. This delicate balancing act requires highly advanced EDA algorithms.
Finally, we must consider Design for Testability (DFT). A chip with a billion transistors will inevitably contain manufacturing defects. Automatic Test Pattern Generation (ATPG) relies on scan chains—where every flip-flop is linked into a massive shift register during test mode—to achieve high fault coverage. Stuck-at-0, stuck-at-1, and transition delay fault models are rigorously tested on the ATE (Automated Test Equipment) before the silicon is packaged and shipped to the customer.
Below is an example of an advanced SystemVerilog assertion used in formal verification to ensure a request signal is always followed by an acknowledge signal within 5 clock cycles:
property req_ack_handshake;
    @(posedge clk) disable iff (!rst_n)
    $rose(req) |-> ##[1:5] $rose(ack);
endproperty
assert property (req_ack_handshake) else $error("Protocol Violation: No ACK received!");
The integration of these methodologies—from robust RTL design to rigorous verification, timing closure, and DFT—forms the backbone of modern hardware engineering. Every module, whether a simple counter or a complex out-of-order CPU core, must pass through this gauntlet before it can be etched into silicon.